Daily Summary of AI · Live edition, updated continuouslySunday 22 November 2026 · UTC
Latest AI News Today: 22 November 2026
METR warns of AI acceleration as providers leak keys and agents fall short
METR warned that AI research gains may outpace safety testing, with the length of tasks models can handle doubling every 3.6 months and public data unable to rule out drastic acceleration. Security researchers found at least three AI inference providers compromised, with attackers harvesting AWS keys and snooping on user data. A simulated workplace test found that even Opus 5.5 and Astra completed fewer than one in ten tasks completely.
AI coding agents ace isolated tests but rarely finish workplace tasks
A new simulated workplace test puts AI coding agents in a developer job with colleagues, project boards and chat histories. Even Opus 5.5 and Astra fully complete fewer than one in ten tasks, but the models are nearing top scores on standard benchmarks.
Perplexity adds Monitor API to wake agents on relevant web changes
Perplexity is expanding its developer business with a Monitor API that watches scheduled web searches and up to 10 pages, sending signed webhooks only when a decision model meets thresholds set by developers. In early internal tests over 60 topics, Perplexity says it delivered 63 fresh relevant pages in eight hours, versus 20 for Firecrawl, 15 for Exa and 10 each for Parallel Core and Lite.
METR warns AI research gains may outpace safety testing
METR says AI models are improving quickly on coding and computational tasks, with the length of tasks they can handle doubling every 3.6 months. The organization warns current public data cannot rule out a drastic acceleration in AI research, which could leave humans unable to assess catastrophic risks. It also cautions that common tests may overestimate real world performance because models are trained in similar environments.
Lean and Mathlib community confirms Alpöge's Riemann proof is correct
The Lean and Mathlib community confirmed that Stanford mathematician Levent Alpöge's proof of the Riemann hypothesis is correct. Alpöge published the proof on Nov. 20, 2026, as 17 million lines of Lean code, and dozens of people independently ran the checks and got the same result. The verification programs are designed so they provably cannot accept a flawed proof. The hypothesis had been one of the most famous unsolved problems in math.
Wells Fargo warns customers that use of AI agents is at their own risk
Wells Fargo will start Tuesday with terms telling customers that use of any AI agent is at their own risk. It joins JPMorgan Chase, Bank of America, Citibank and PNC in new terms or warnings as agents automate logins, purchases and other online tasks. Amazon blocked Meta's Muse from buying on its site, and United says personal bots cannot buy flights. Pushback matters because automation is agents' main appeal, but it can create security risks.
Google previews Tool Retrieval in Gemini API for large tool libraries
Google has previewed Tool Retrieval in the Gemini API, letting agents keep large tool libraries available without sending every parameter schema in each prompt. The model sees only tool names and short descriptions, then requests full schemas when a task needs a tool, reducing token use from dozens of function declarations. Server-side search is default; client-side mode lets developers run their own lookup, with MCP tools and standard billing.
GPT-6.2 Astra and Sol are shorter and less transparent than Claude
Artificial Analysis found OpenAI's GPT-6.2 Astra and Sol give much shorter, more direct answers than their predecessors, with average lengths falling from 352 to 210 words for Astra and from 337 to 223 for Sol. Their scores for admitting uncertainty dropped sharply, and both trailed Anthropic's Claude Fable 5.2 and Opus 5.5 on a transparency index. The evaluation shows a shift toward brevity and directness while transparency scores lag.
Berlin arts complex apologises over military AI event
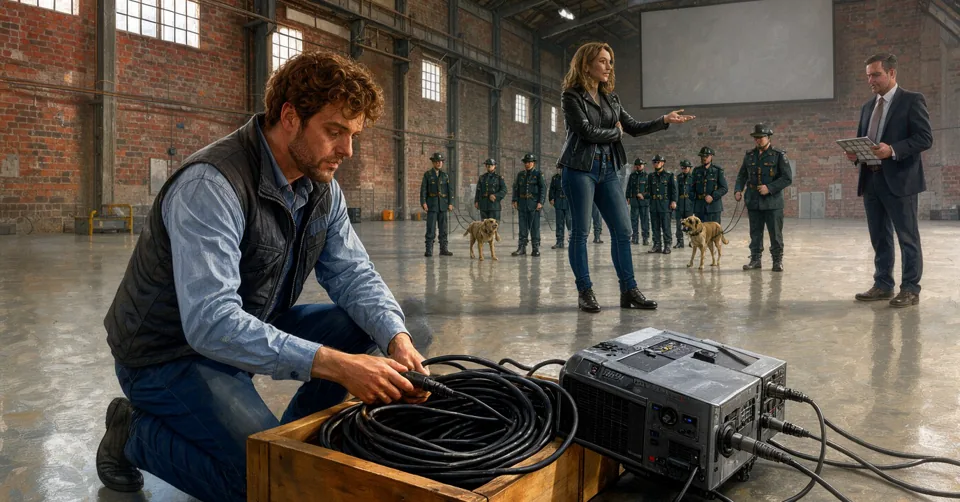
Kraftwerk Berlin has apologised for a serious error of judgment after transforming its central hall into a war room for the launch of Clarity, an AI targeting system by German arms startup Helsing. The 11 November event featured maps, aerial footage, drones and guards with sniffer dogs, drawing criticism from Berlin's music scene. The row raised questions about the commercialisation of the city's nightlife and its traditional pacifism.
South Korea education minister resigns over AI exam cheating
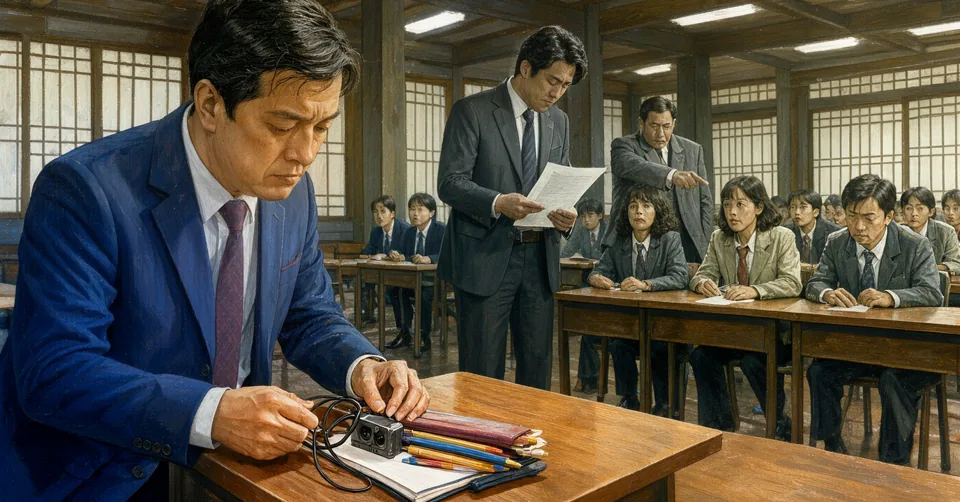
South Korea's education minister Choi Kyo-jin resigned Sunday after an AI-assisted cheating scandal before the suneung, the exam that shapes university and career prospects. President Lee Jae Myung accepted his resignation after a top tax accountant exam scorer confessed to using a miniature camera and smartphone for a near-perfect score.
TensorLean verifies GPU kernels and finds 38 correctness bugs
Researchers from Columbia University and CertiK introduced TensorLean, a Lean-based framework that formally verifies GPU kernels at the PTX level. It proves compiled kernels match a tensor-level spec by proving no data races, termination, correct output within tolerance and untouched memory. The team checked 149 kernel instances, including all FlashAttention-2, -3 and -4 kernels plus DeepGEMM, proved 83 correct and found 38 bugs.
 Illustration